


Reliability Engineering
From Visibility to Resilience
After gaining visibility into your infrastructure and applications, the next step is using those insights to improve system behavior, operational processes, and service outcomes.
Our reliability engineering services help organizations:
- Reduce downtime and service disruptions
- Improve application and infrastructure performance
- Establish measurable reliability objectives
- Automate detection and recovery workflows
- Strengthen operational readiness
- Build scalable systems that support growth
Core Reliability Engineering Services
Design resilient infrastructure and application architectures that minimize single points of failure.

Service Level Indicators and Objectives (SLIs/SLOs)
Incident Management and Response

Performance Optimization

Automation and Self-Healing
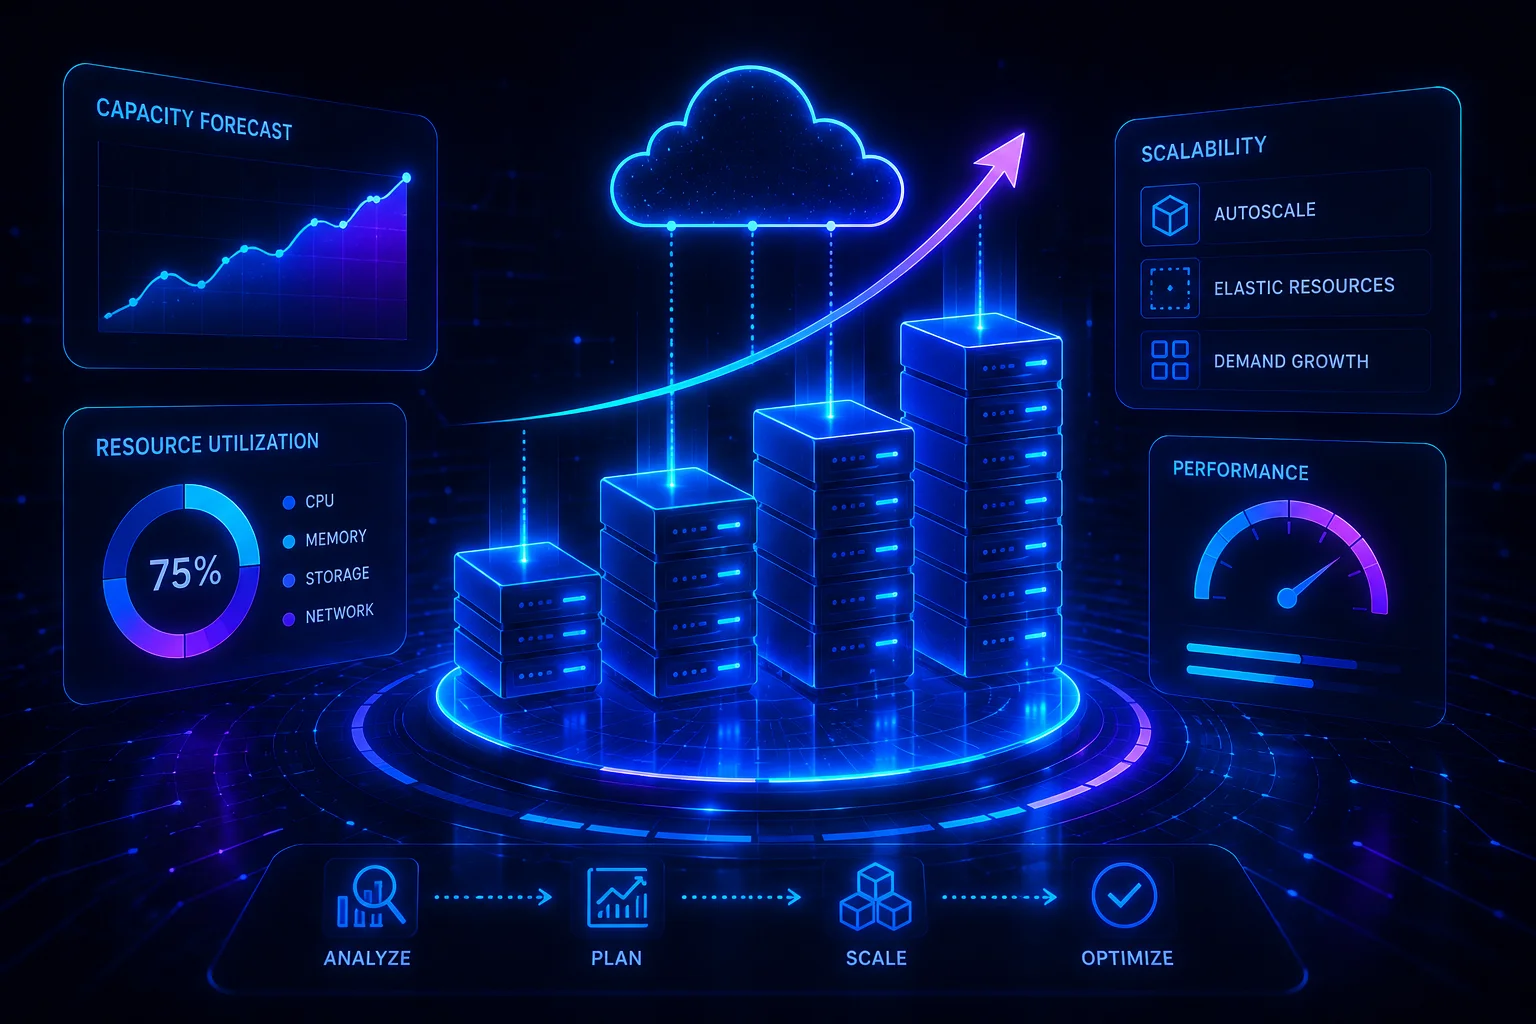
Capacity Planning and Scalability

Root Cause Analysis
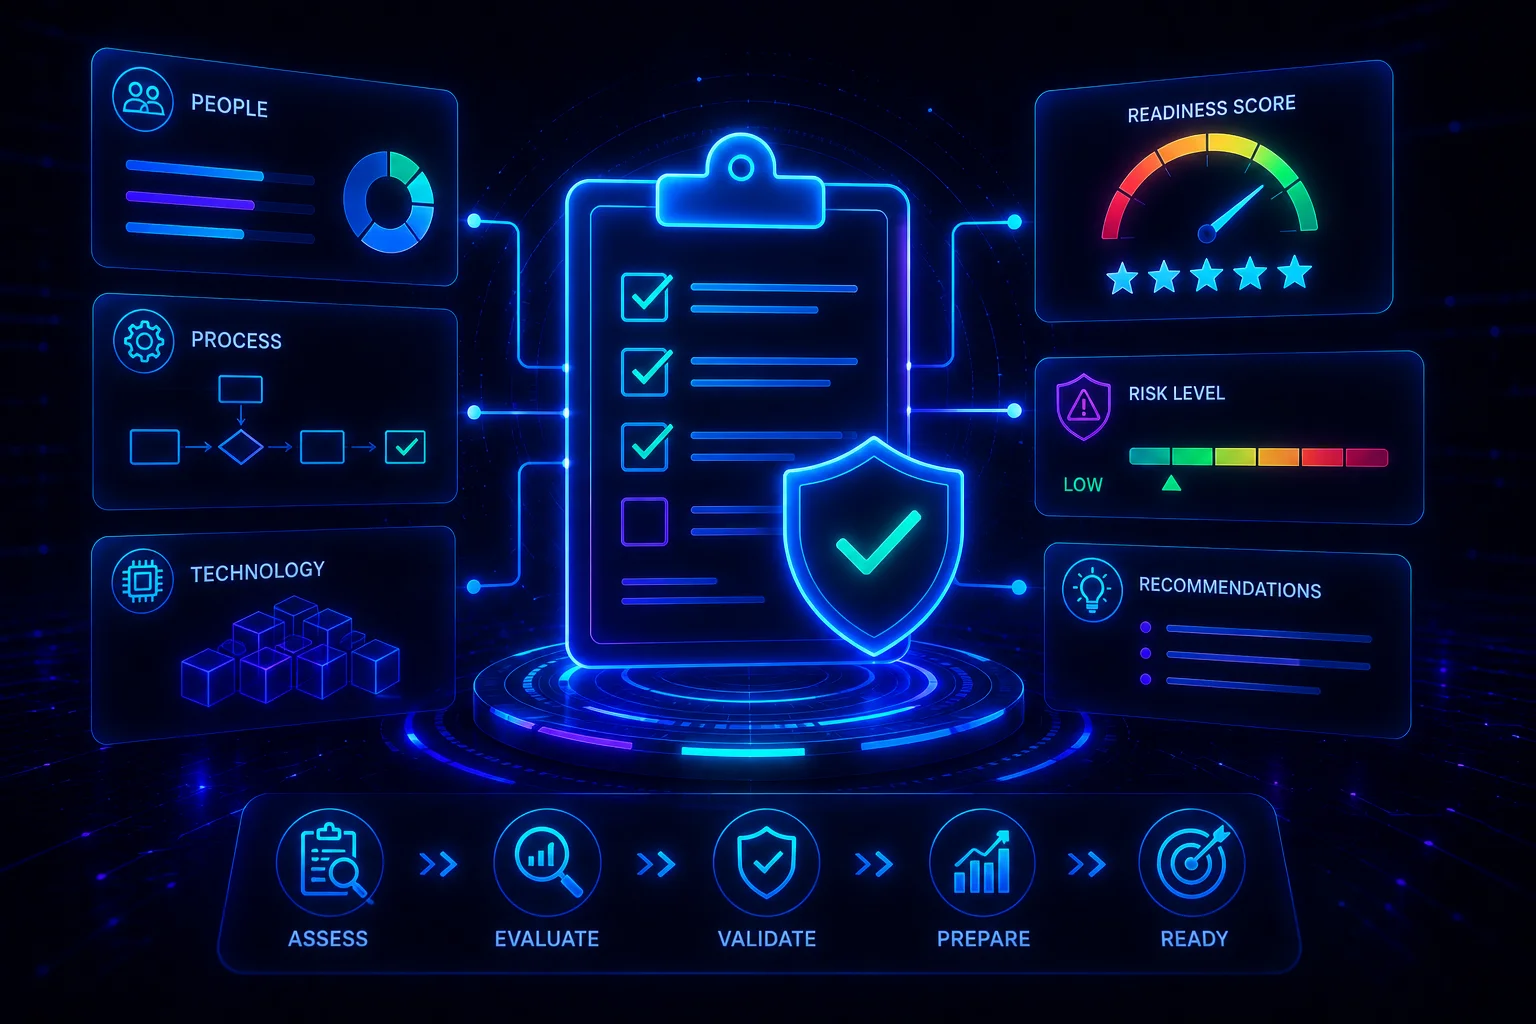
Operational Readiness Assessments
Reliability Engineering Outcomes
Organizations that adopt reliability engineering practices typically achieve:
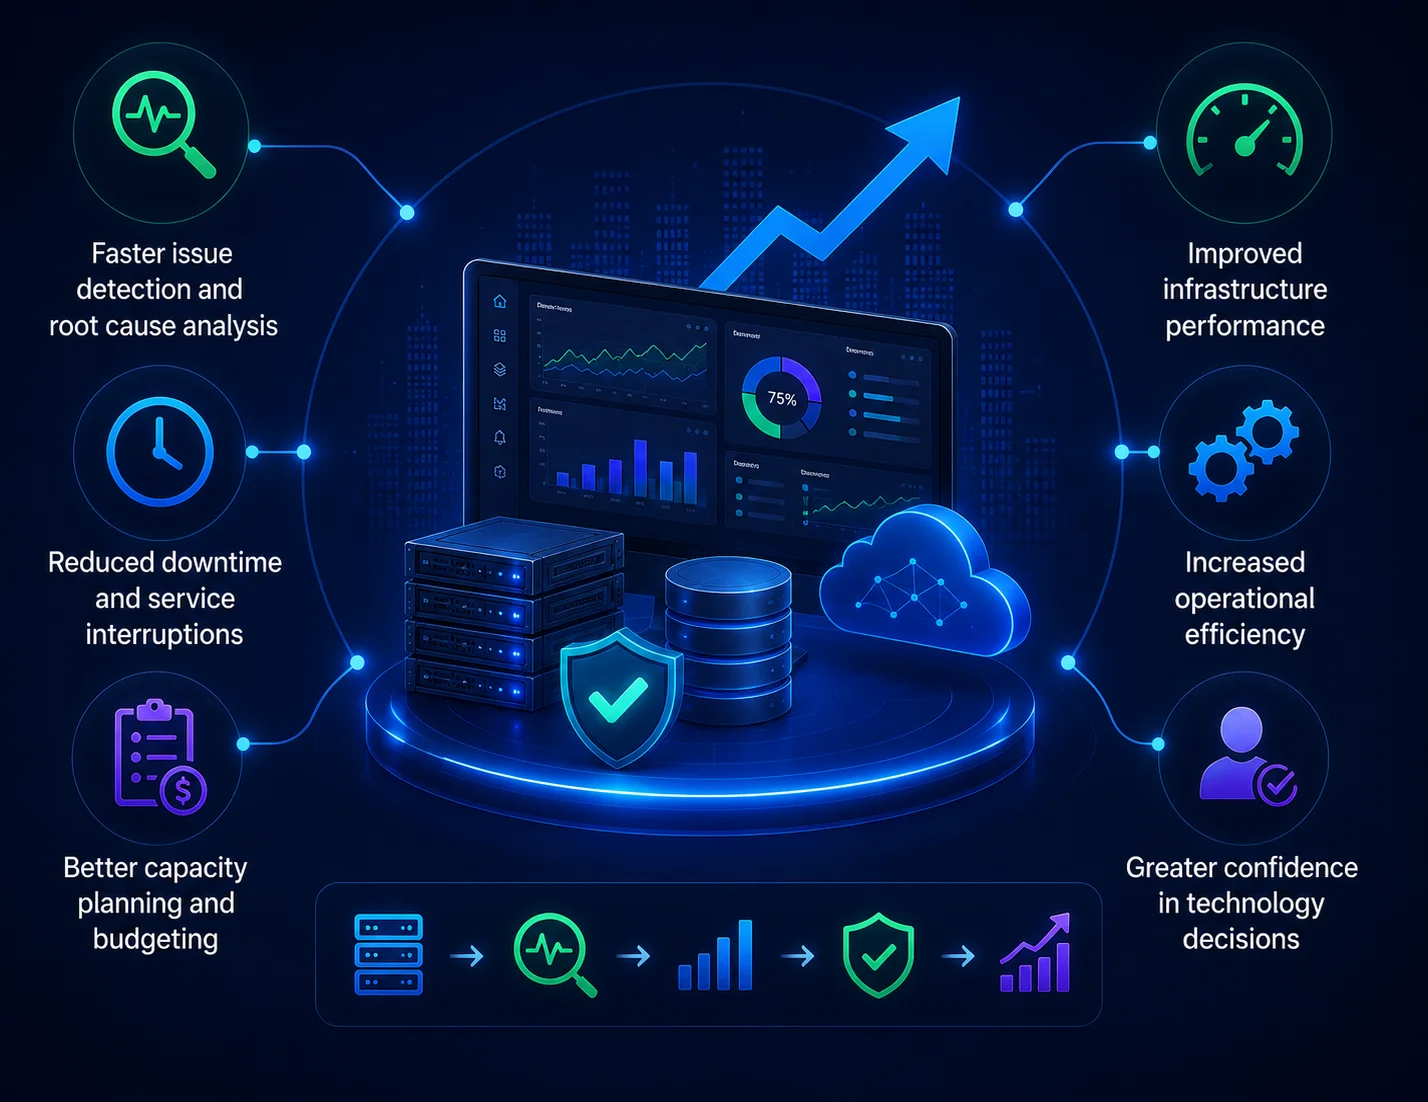
Reduced downtime and unplanned outages
Faster incident detection and resolution
Improved system stability and performance
Clear service-level expectations
Greater automation and operational efficiency
Increased confidence during peak demand and change events
Reliability Metrics That Matter
- Service Level Indicators (SLIs)
- Service Level Objectives (SLOs)
- Error budgets
- Availability and uptime
- Mean Time to Detect (MTTD)
- Mean Time to Resolution (MTTR)
- Capacity utilization and saturation
- Change failure rate
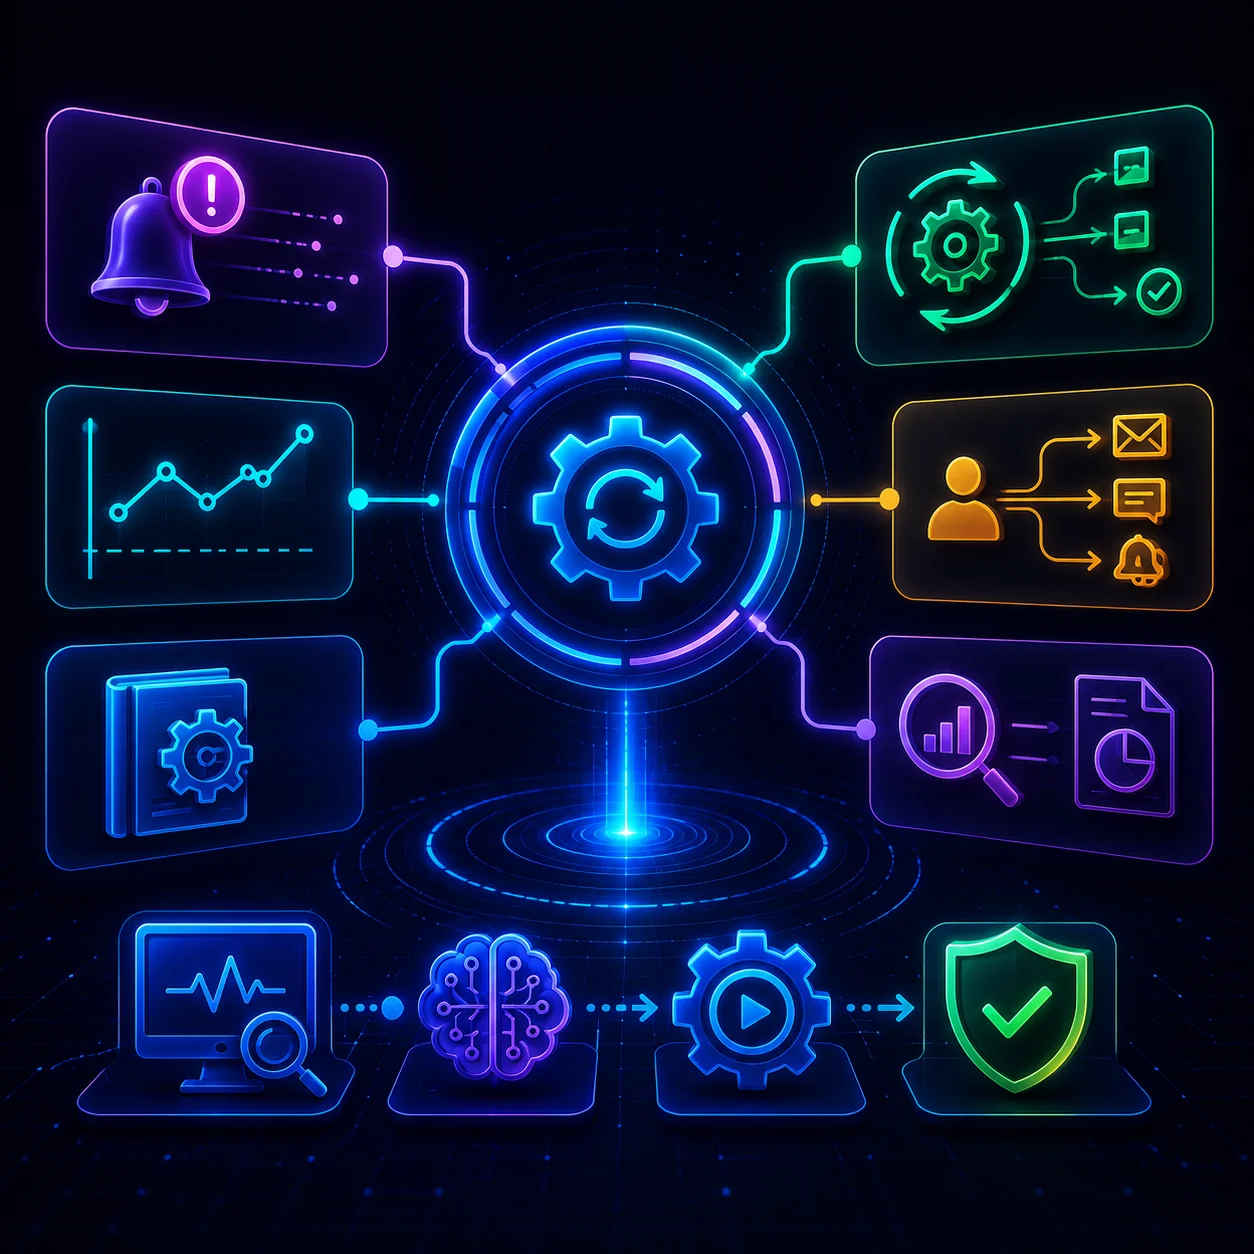
Automation and Self-Healing Operations
- Automated alert correlation
- Dynamic thresholding
- Runbook automation
- Auto-remediation workflows
- Incident enrichment and routing
- Post-incident analysis and reporting
Why Fullhouse Technologies
- Observability and monitoring specialists
- Performance and capacity experts
- Automation and integration engineers
- Reliability-focused architecture and governance
Frequently Asked Questions
Reliability engineering is the practice of designing systems, processes, and operational workflows to maximize availability, performance, and resilience.
Monitoring provides visibility into system behavior. Reliability engineering uses that visibility to improve system design, automation, and operational practices.
Service Level Indicators (SLIs) are metrics that measure service health, while Service Level Objectives (SLOs) define target performance and availability goals.
Yes. We design and deploy automated detection, remediation, and operational workflows to reduce manual effort and accelerate recovery.
Absolutely. Our reliability engineering services are designed for complex, distributed, and mission-critical environments.
Build Systems That Perform Reliably at Scale
Transform observability and operational insight into measurable improvements in availability, resilience, and performance.